

2–3 Years to Build
Traditional data centers require 24–36 months from planning to commissioning. By the time your facility is ready, your GPU architecture is already a generation behind.

The Challenge
The GPU revolution has outpaced traditional data center design. H100 and B200 GPUs demand power densities that break conventional cooling limits — and construction timelines that can’t keep up with AI’s speed of innovation.
2–3 Years to Build
Traditional data centers require 24–36 months from planning to commissioning. By the time your facility is ready, your GPU architecture is already a generation behind.
25 kW — Air Wall
Forced-air cooling simply cannot remove heat fast enough beyond 25kW per rack. NVIDIA H100 clusters routinely exceed 40kW — and B200 pushes past 100kW. Air cooling is no longer an option.
$50M+ Capital Before First GPU
Conventional construction demands massive upfront capital — land acquisition, permits, civil works, MEP infrastructure — all before you rack a single server. This delays ROI and ties up capital for years.
The Platform
One integrated platform that delivers the total AI data center — thermal, power, structure and control — purpose-built around your GPU workload.
Every Soeteck AI data center is factory-built inside standard ISO shipping containers. 95% pre-assembled, tested at our factory, then shipped worldwide. Plug in power, network, and water — compute starts.
Direct-to-chip cold plate technology removes heat at the source. Integrated Coolant Distribution Units (CDUs) handle up to 1.5MW of thermal load per module. PUE as low as 1.08.
From medium-voltage switchgear to intelligent rack PDUs — engineered for 40–120kW per rack. Modular Li-Ion UPS, 800A busway, per-outlet metering.
No vendor lock-in. Full support for NVIDIA H100/H200/B200, AMD MI300X, Huawei Ascend 910B/C, and Intel Gaudi. Choose the GPU that fits your workload and budget.
A single AI infrastructure platform that scales from edge inference to hyperscale clusters.
| Specification | AI-Edge | AI-Core | AI-Flex |
|---|---|---|---|
| Container | 20ft ISO Standard | 40ft High-Cube ISO Standard | 4–20+ interconnected 40ft modules |
| Power | 80–200 kW | 300–600 kW | 2–20 MW |
| GPU Capacity | 8–16 GPUs | 32–64 GPUs | 256–2,048+ GPUs |
| Cooling | Air-cooled standard, liquid optional | Direct-to-chip CDU integrated | Centralized liquid + optional immersion |
| Rack Density | Up to 30 kW | Up to 100 kW | Up to 120 kW |
| PUE | 1.15–1.25 | 1.08–1.15 | < 1.10 (1.03 immersion) |
| Deployment | 60–90 days | 90–120 days | 120–180 days |
| Best For | Edge inference, smart manufacturing, 5G edge | LLM training, fine-tuning, research clusters | Hyperscale AI, AI clouds, national computing |
Edge Inference
Best For: Edge AI inference, smart manufacturing, telecom 5G edge, retail AI
Inquire About AI-Edge →Training & Fine-Tuning
Best For: Enterprise LLM training, AI model fine-tuning, university research clusters
Inquire About AI-Core →Hyperscale Clusters
Best For: Hyperscale AI training, AI cloud service providers, national AI computing centers
Inquire About AI-Flex →Cooling
The physics is simple: liquid coolants offer over 3,000× more heat removal capacity per unit volume than air. Every hyperscaler is transitioning to liquid cooling. The only question is how fast.
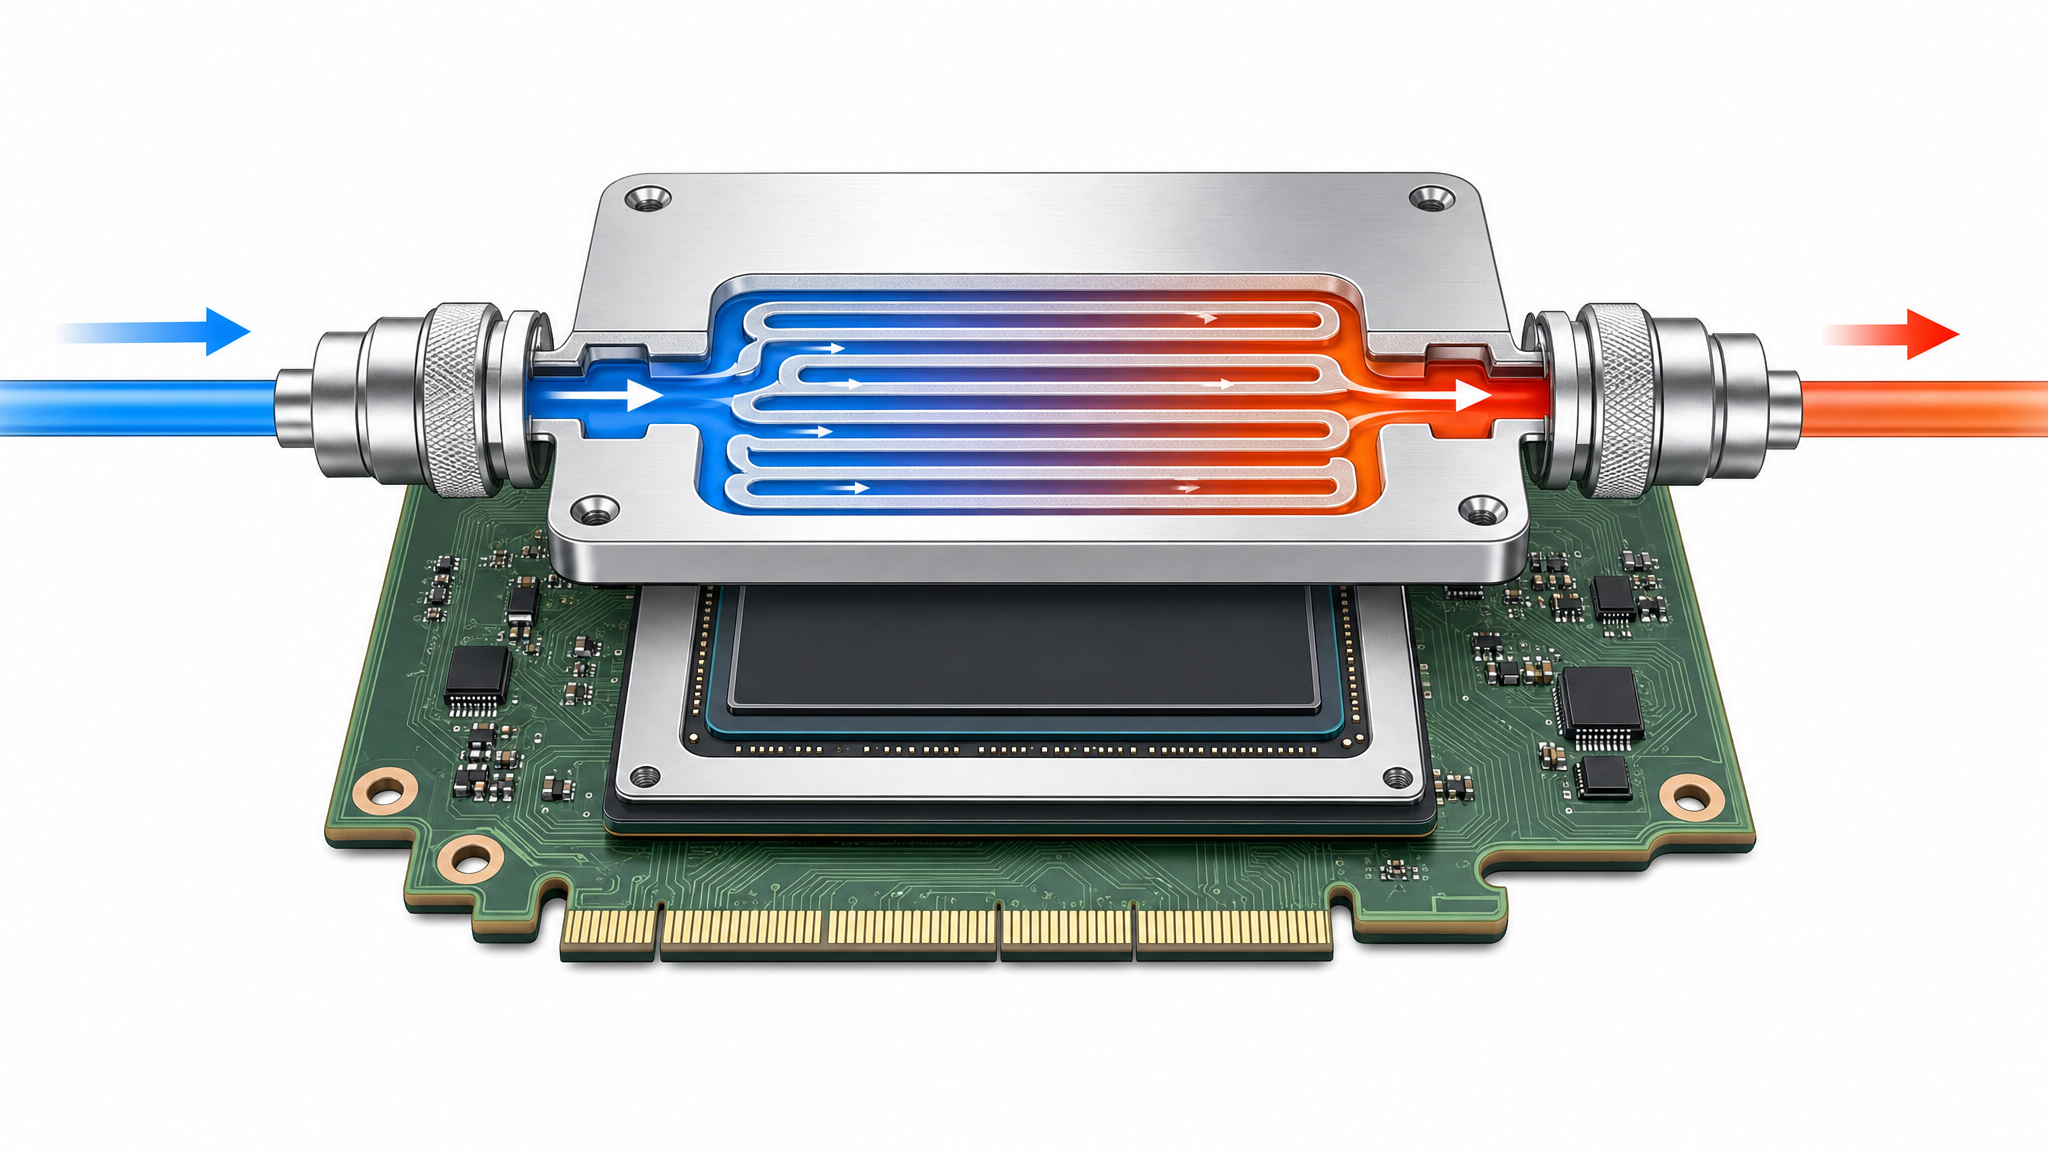
Direct-to-chip liquid cooling is the workhorse of modern AI infrastructure. Cold plates mount directly onto GPU and CPU heat spreaders, circulating a dielectric coolant through micro-channel fins to remove heat at the source.
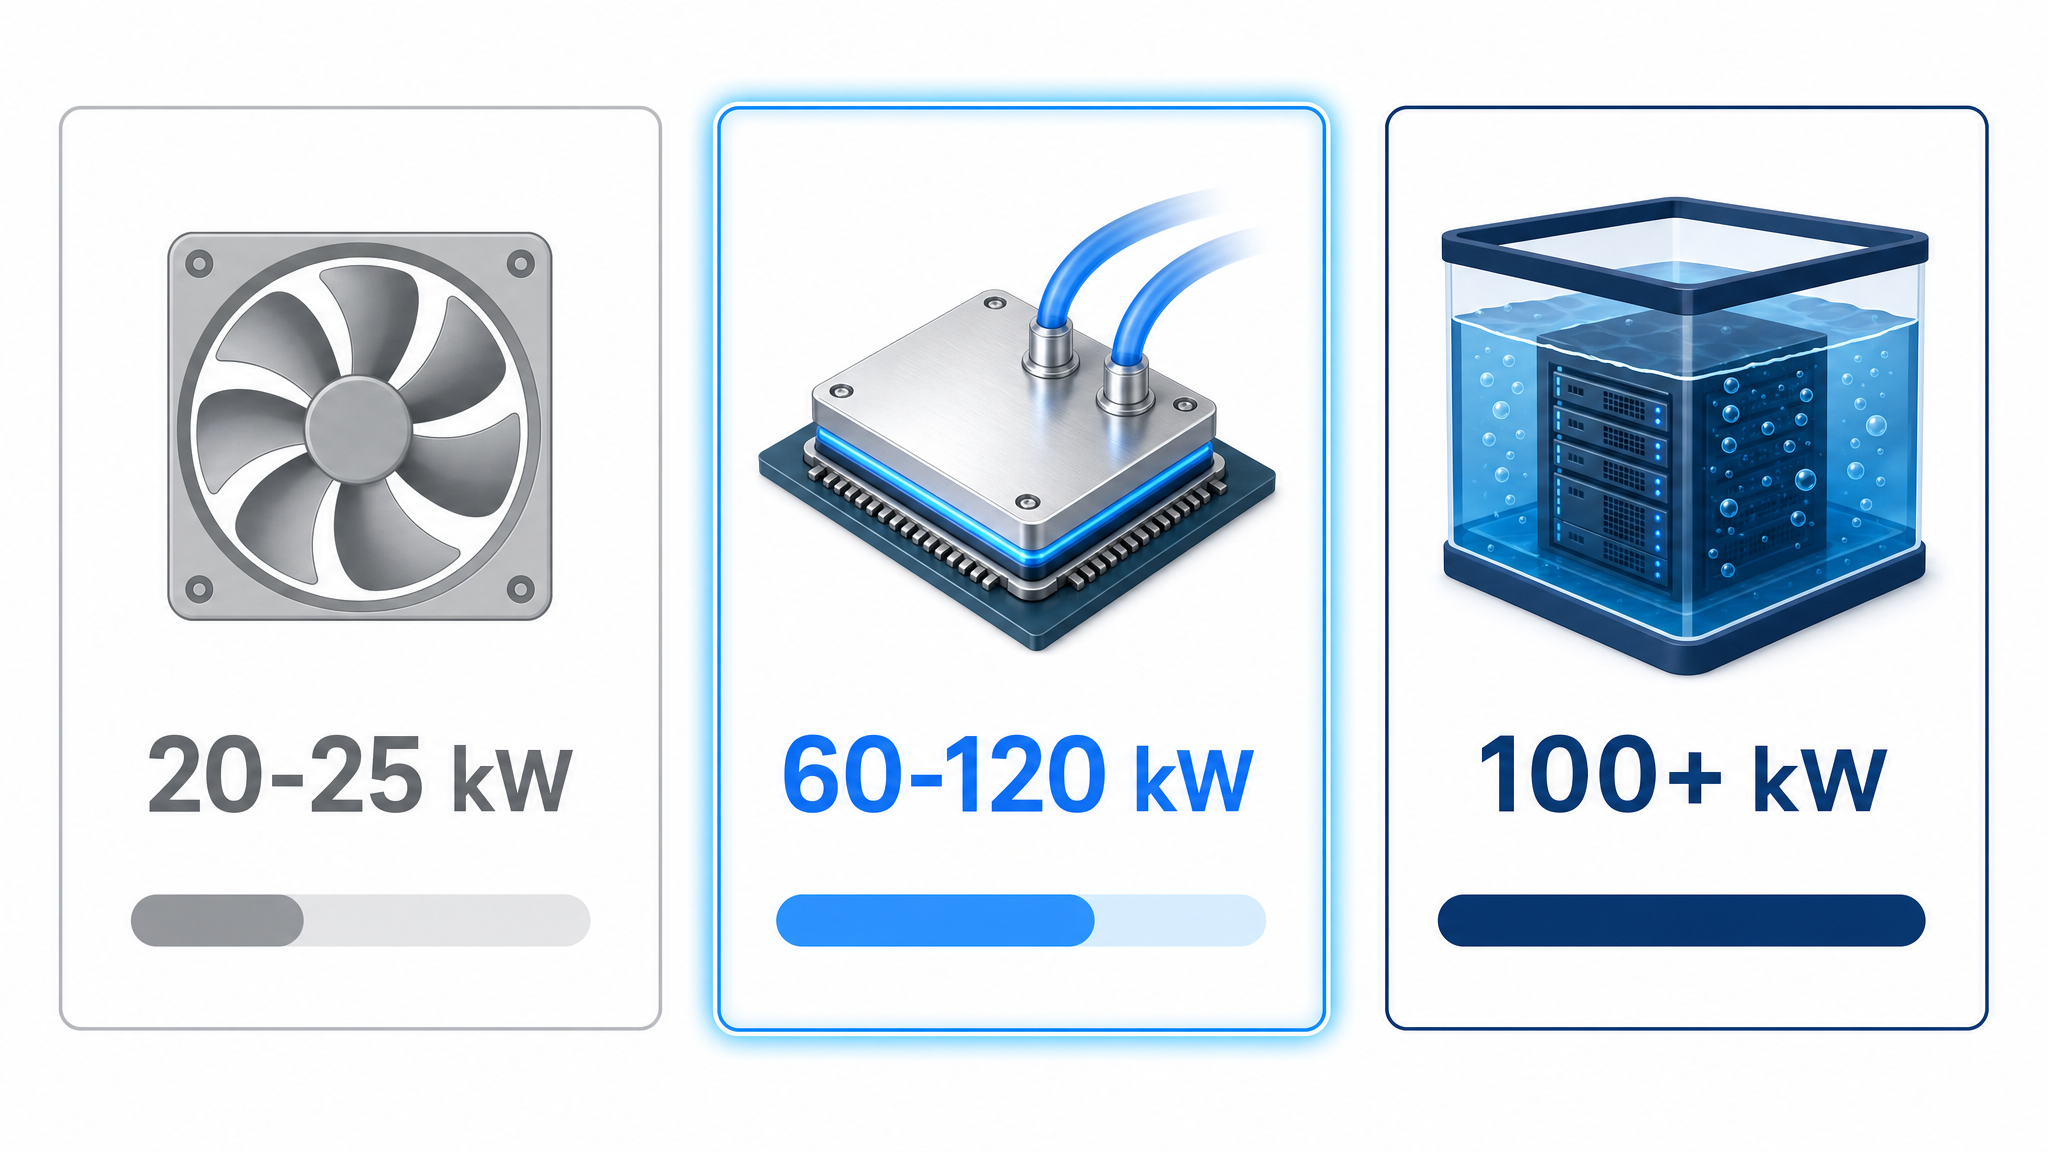
For the highest-density deployments, single-phase immersion cooling submerges entire GPU servers in a dielectric fluid that absorbs heat 1,200× more efficiently than air.
Air has a volumetric heat capacity of ~1.2 kJ/m³·K. Liquid coolants offer 3,500–4,200 kJ/m³·K — over 3,000× more heat removal capacity per unit volume.
Power
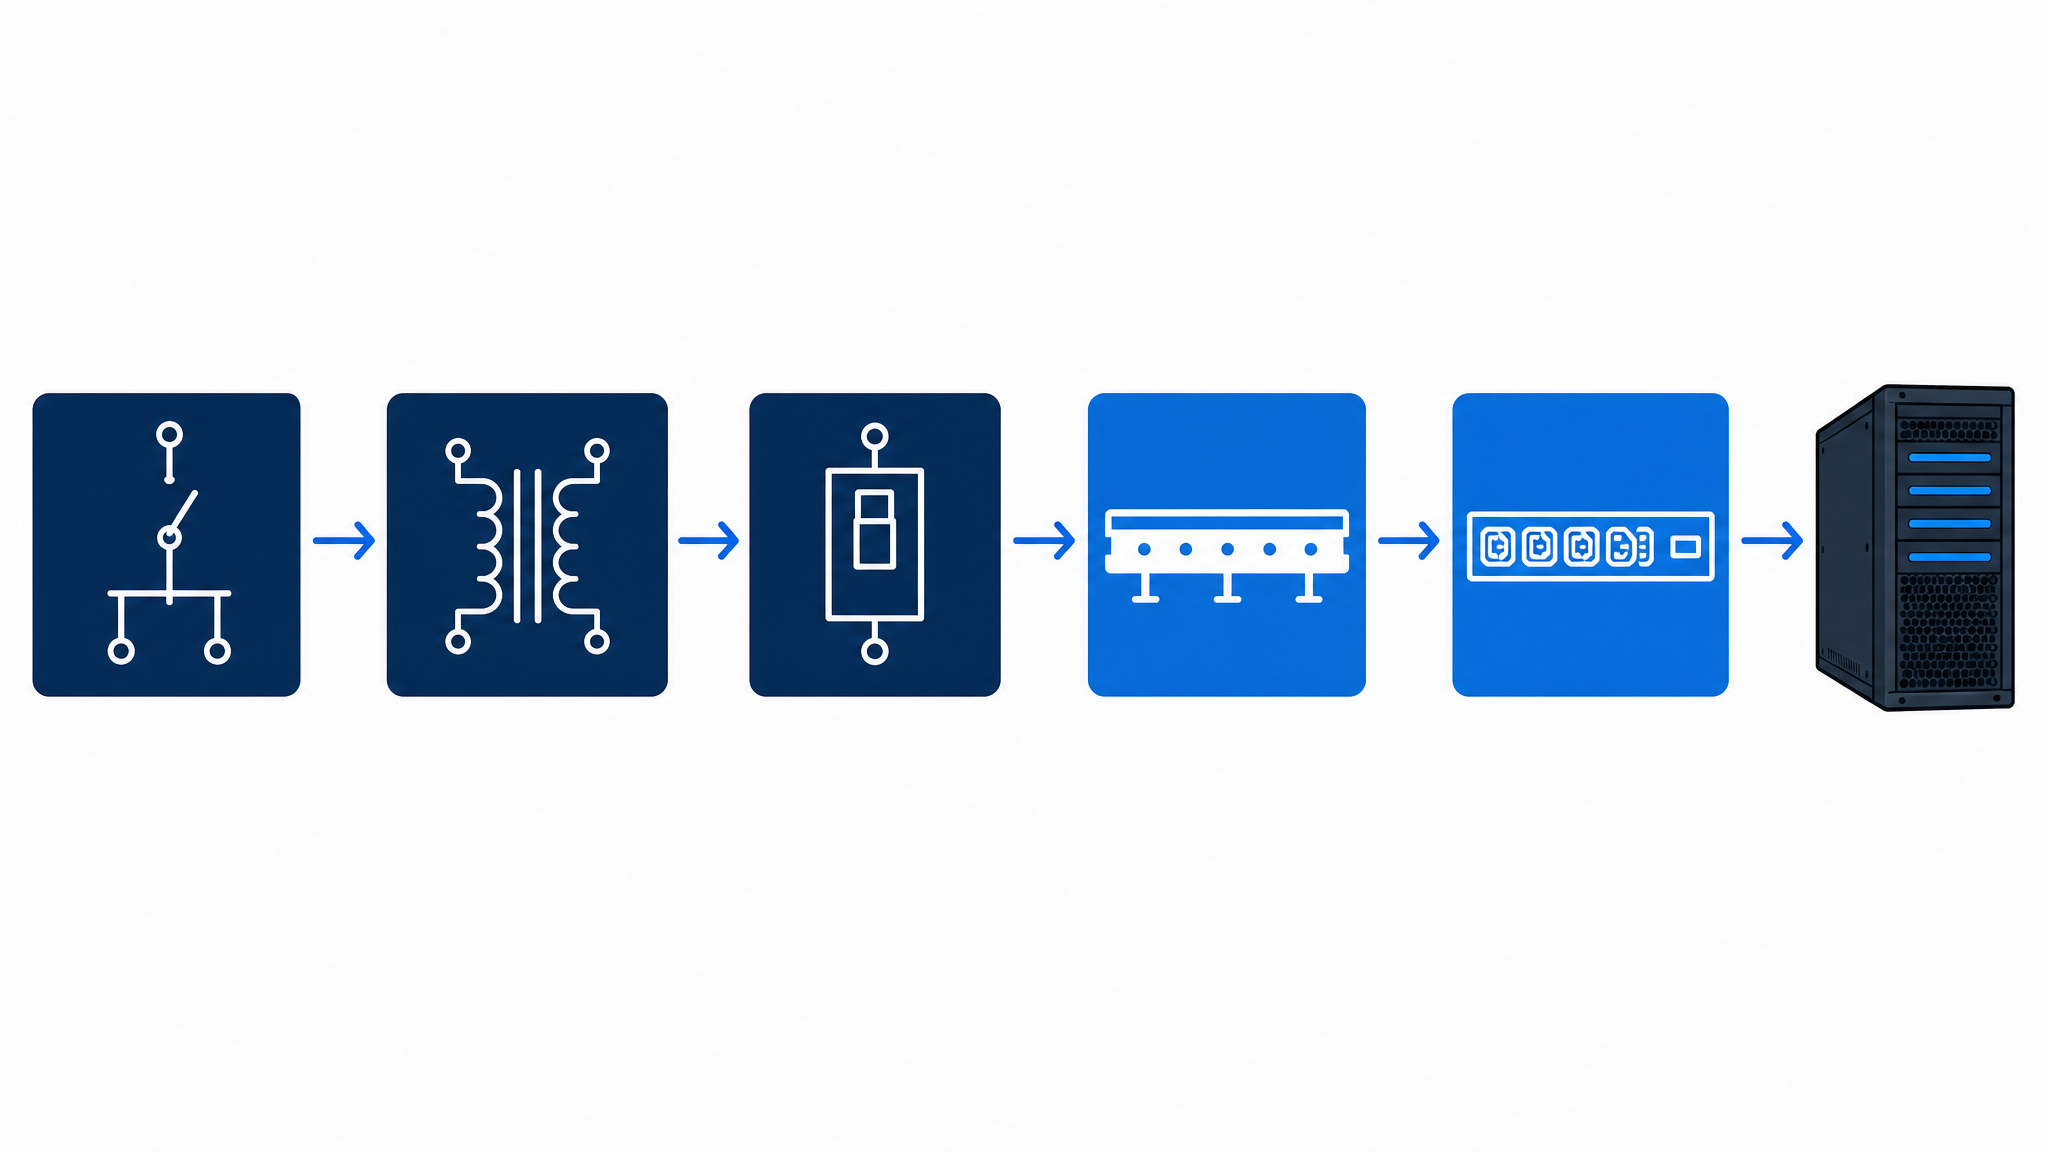
GPU clusters don’t just need more power — they need power delivered differently. Our integrated power distribution chain is designed from the ground up for high-density, mission-critical AI workloads.
Li-Ion battery technology, N+1 or 2N redundancy, 98% efficiency in eco-mode. Scalable from 100kW to 2MW per module. Hot-swappable battery modules with integrated Battery Management System (BMS).
160A–800A overhead busway with tap-off boxes every 600mm. Eliminates under-floor cabling complexity. Hot-swappable tap-offs allow adding or relocating GPU racks without shutdowns.
Per-outlet power metering (±1% accuracy), remote outlet switching, integrated environmental sensors (temperature, humidity, door contact). SNMP v3 + REST API for integration with DCIM and BMS platforms.
Speed to Compute
From order to operational GPUs in 90–120 days, compared to 24–36 months for a traditional build.
Requirements confirmed. GPU selection finalized. Power design signed off.
Container fabricated. Cooling CDU integrated. Full system tested at our factory.
Port-to-site logistics managed. Customs clearance handled by our global freight partners.
Plug in power, network, water. Acceptance testing. Operator training. Compute starts.
Global Logistics
Soeteck AI data centers are purpose-designed for global logistics. Built into standard ISO shipping containers, they travel on existing freight infrastructure — container ships, flatbed trucks, and cargo aircraft. Every unit undergoes full factory acceptance testing (FAT) before leaving our facility. When it arrives at your site, it’s ready to commission — not assemble.
Custom containerized data center for 24/7 stable operations in Middle Eastern climate.
Read the case study →Factory audit and major digital infrastructure project for government data center modernization.
Read the case study →Mobile OLT container data center solution enabling rapid 5G infrastructure deployment.
Read the case study →Data center cooling infrastructure optimization delivering improved efficiency and reliability.
Read the case study →Our direct-to-chip liquid-cooled containers support up to 120 kW per rack. Immersion cooling modules support 100+ kW per rack with no derating. Air-cooled configurations are available up to 25 kW per rack for lighter workloads.
Our infrastructure is GPU-agnostic by design. We support NVIDIA H100, H200, B200 (NVL72), AMD MI300X, Huawei Ascend 910B/C, and Intel Gaudi 3. Power shelves and cold plate mounting kits are customized to your chosen GPU platform.
90–120 days from order to commissioning for standard configurations up to 5 MW. Custom configurations and hyperscale AI-Flex deployments may take 120–180 days. This compares to 24–36 months for traditional data center construction.
We implement a defense-in-depth approach: (1) negative-pressure coolant loops (fluid is drawn back into the system on any breach), (2) rope-style leak detection cables along all pipe runs, (3) stainless steel drip trays under all connections, (4) 24/7 monitored conductivity sensors with automatic shutoff valves, (5) non-conductive PG25 propylene glycol coolant that won’t damage electronics on contact.
Direct-to-chip liquid cooling: PUE 1.08–1.15 depending on climate. Immersion cooling: PUE as low as 1.03. Both figures assume free cooling with dry coolers where climate permits.
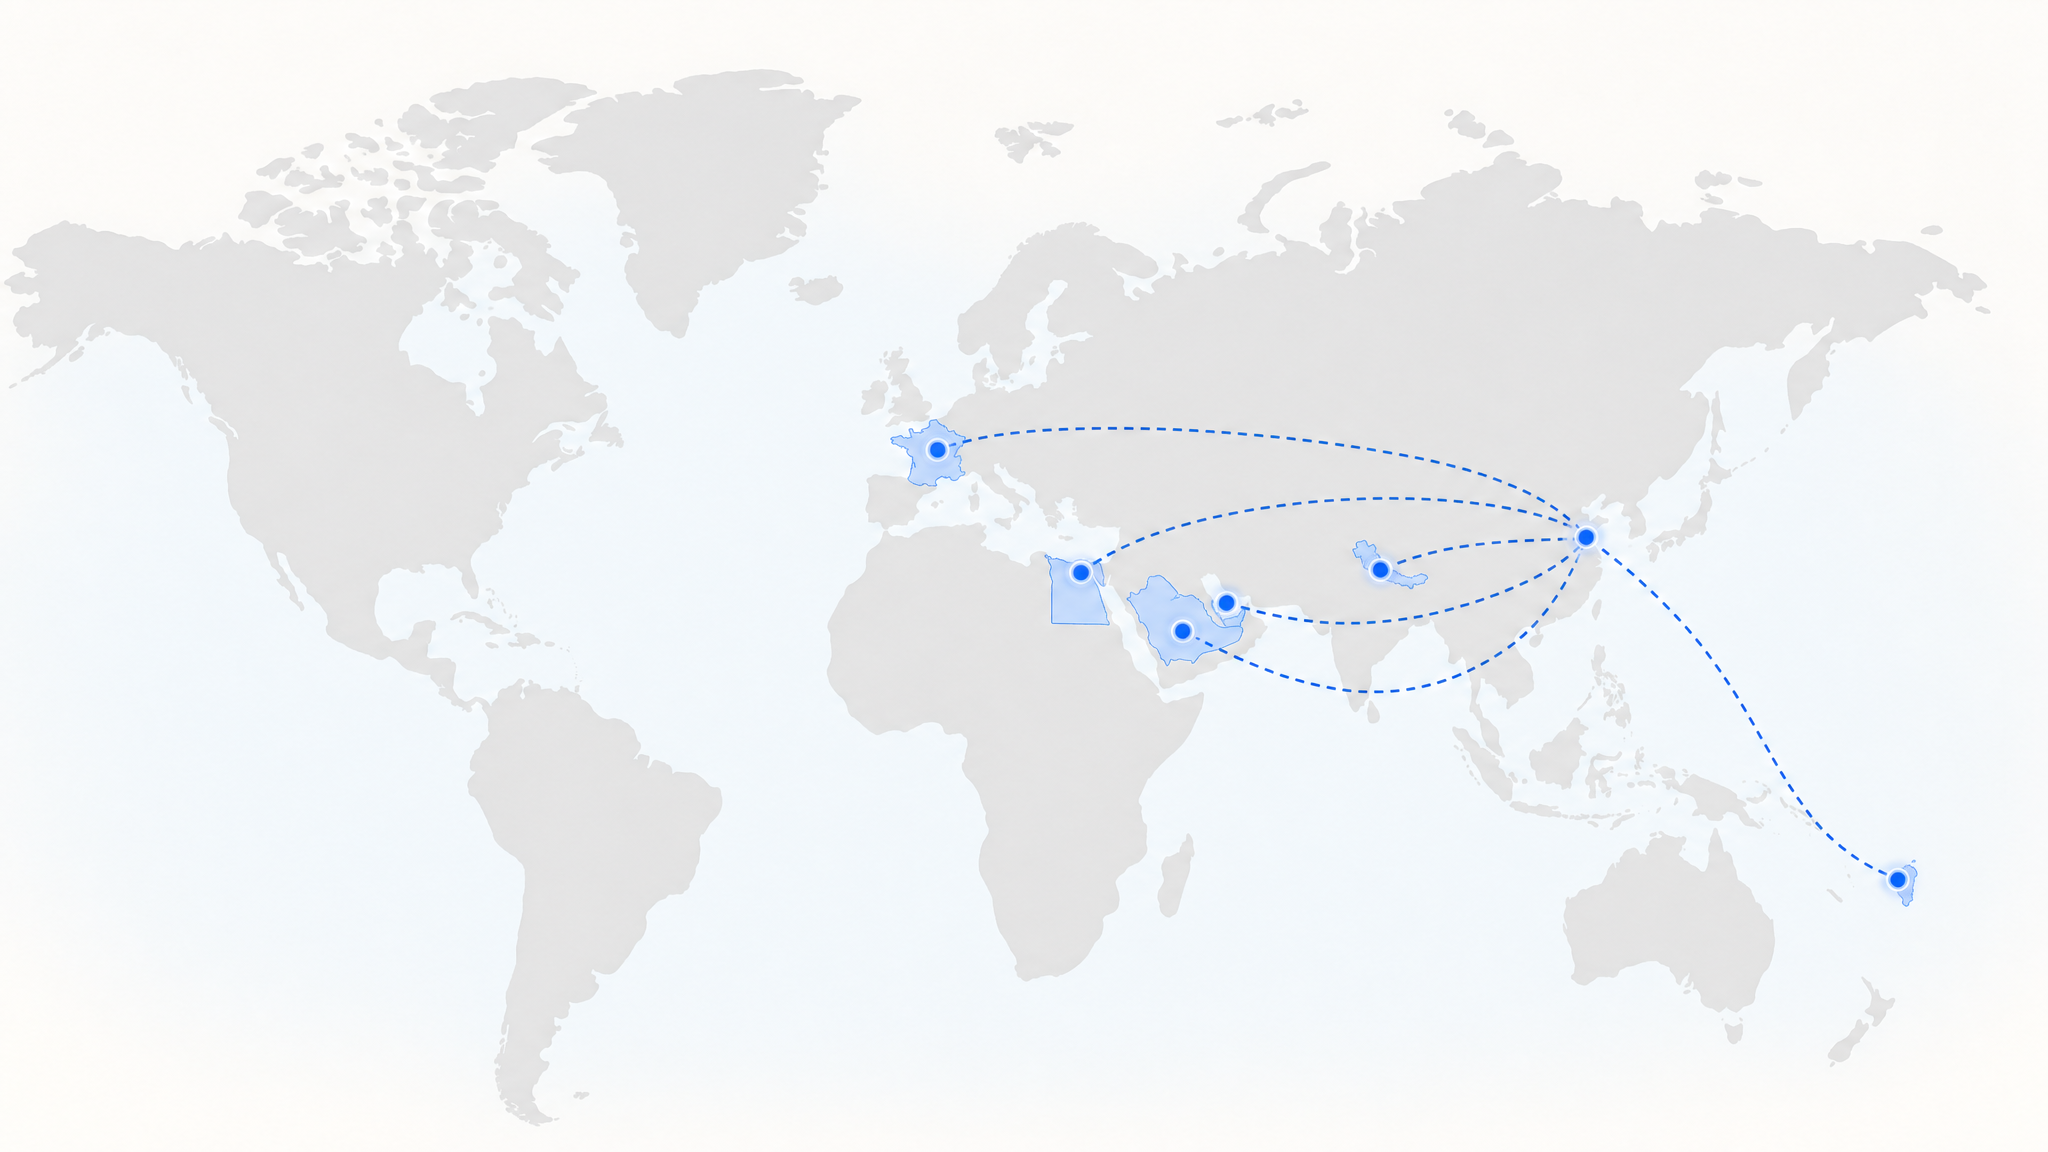
Yes. Our containers are rated for ambient temperatures from -40°C to +55°C (+131°F). We have deployed successfully in Middle Eastern desert environments (Saudi Arabia, Qatar, Egypt) and tropical island conditions (Vanuatu). Each deployment includes climate-specific cooling configurations.
Yes. Our global commissioning team travels to your site for installation supervision, system startup, acceptance testing, and operator training. We also offer optional annual maintenance contracts with remote monitoring (24/7 NOC), preventive maintenance visits, and emergency response SLAs.
Talk to an Engineer
Share your facility requirements and get a practical solution path. Tell us your project type, capacity needs, and timeline — our team will help identify the right configuration.